Running AI models directly on the user's device saves cloud costs and protects privacy. But forcing heavy WebGPU or WebNN workloads on low-end hardware will freeze the UI. Safely orchestrate local AI with the AI Readiness (AIR) Index.
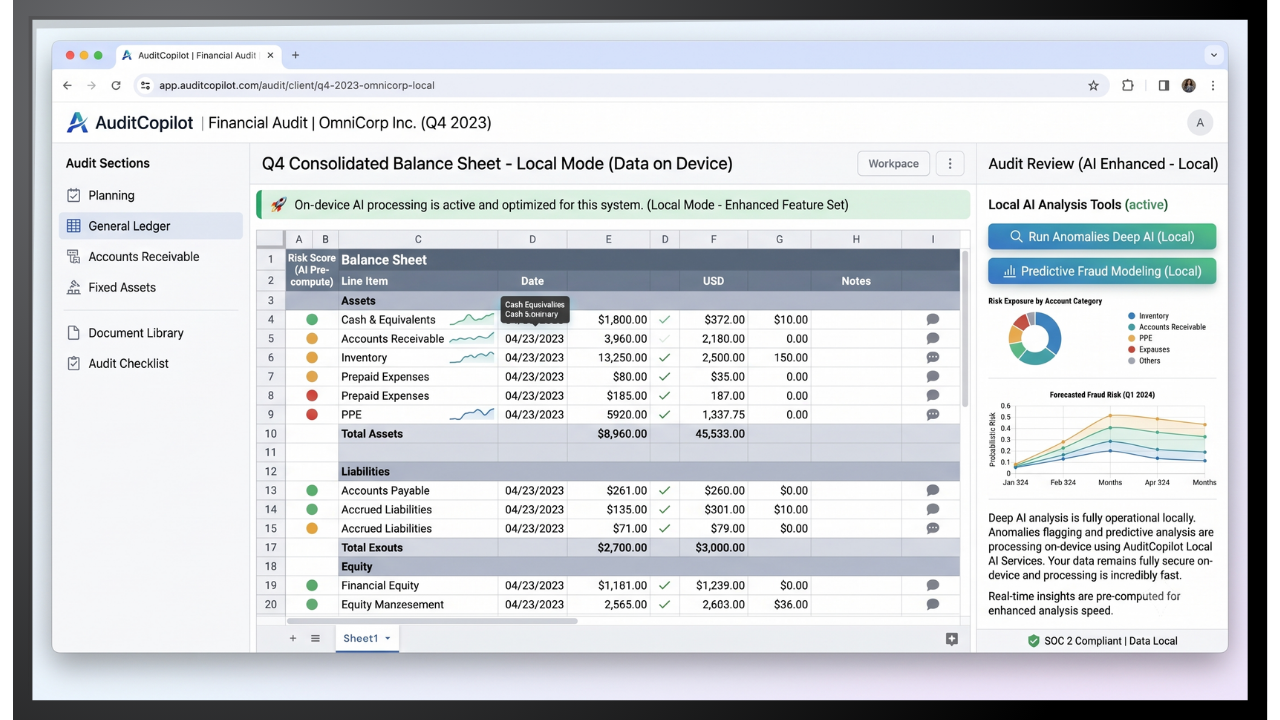

Sending every prompt or image to a cloud server (via API) creates massive latency, explodes your infrastructure costs, and raises severe data privacy (GDPR) concerns.
Executing models (like local LLMs or computer vision) directly in the browser via WebGPU is the future. But deploying a 2GB model on a 4GB RAM smartphone will result in an immediate Out-Of-Memory (OOM) crash and a lost user.
Our engine evaluates the specific Neural Processing Unit (NPU), GPU compute power, and available RAM of the user's device in milliseconds before any model is downloaded.
Build resilient apps. If the AIR score is high (Premium device), execute the AI model locally for zero-latency, zero-cost processing. If the score is low, automatically fallback to your Cloud API.
Whether you are using TensorFlow.js, ONNX Runtime Web, or WebNN APIs, Impulse Engine ensures your models only run on hardware capable of sustaining them.
Run document summarization or local AI assistants directly on the client's machine. Zero sensitive data leaves their browser.
Activate Virtual Try-On, real-time background removal, or local semantic search only on devices that can render it at 60 FPS.
Offload up to 60% of your AI API calls directly to your users' hardware, drastically cutting your OpenAI or AWS bills.
Don't build expensive local AI features blindly. Deploy our passive tracker via GTM. We will scan your live traffic and deliver a report showing the exact percentage of your users with the NPU/GPU capacity to run local models safely
Zero Dev Integration:
Simple drop-in via Google Tag Manager.
100% Privacy First:
GDPR compliant, zero cookies, zero PII.
Enterprise-Grade Accuracy: Powered by speedpower.run global telemetry.